Motion
Builds
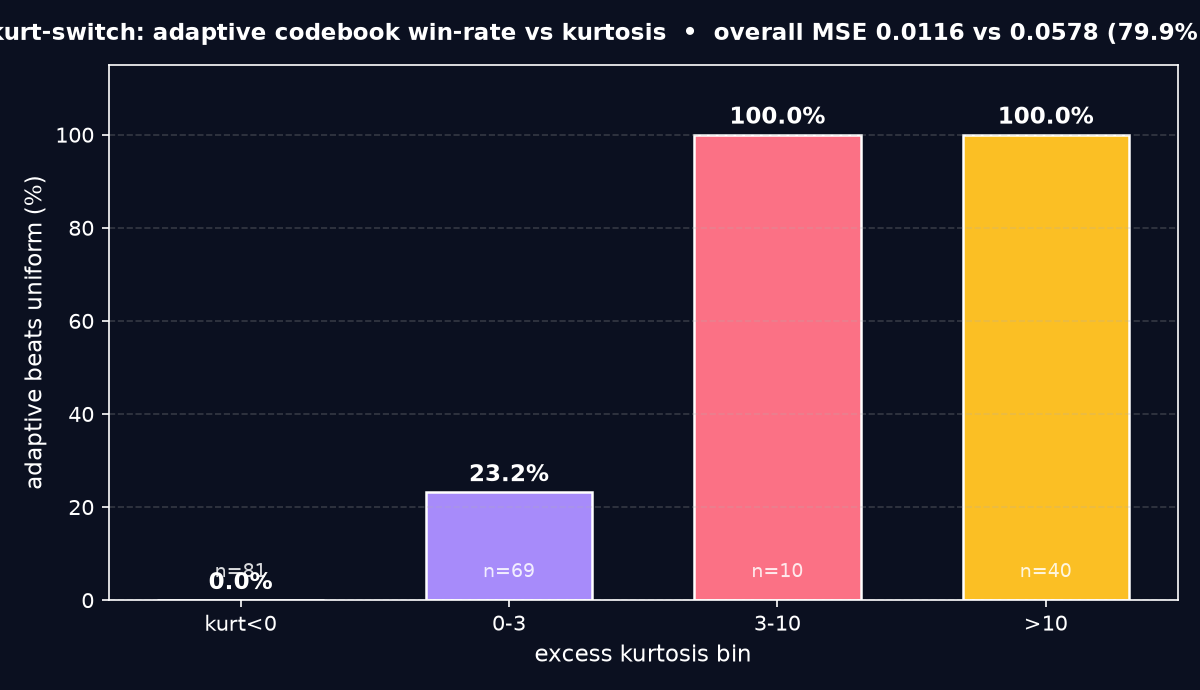
kurt-switch
79.9% lower MSE vs static codebook
How it works
Per-row kurtosis + sparsity switch among 3 codebooks (uniform / odd companded / shifted) with closed-form LS scale.
Implementation
kurt_switch/core.py: compute_row_stats, select_codebook, quantize_row. 5 tests.
Applications
On-device LLM weights, Q4 serving where outlier rows kill quality.
Prior art: GPTQ/AWQ + Grouped Lattice VQ 2510.20984 + r/LocalLLaMA 4-bit bench
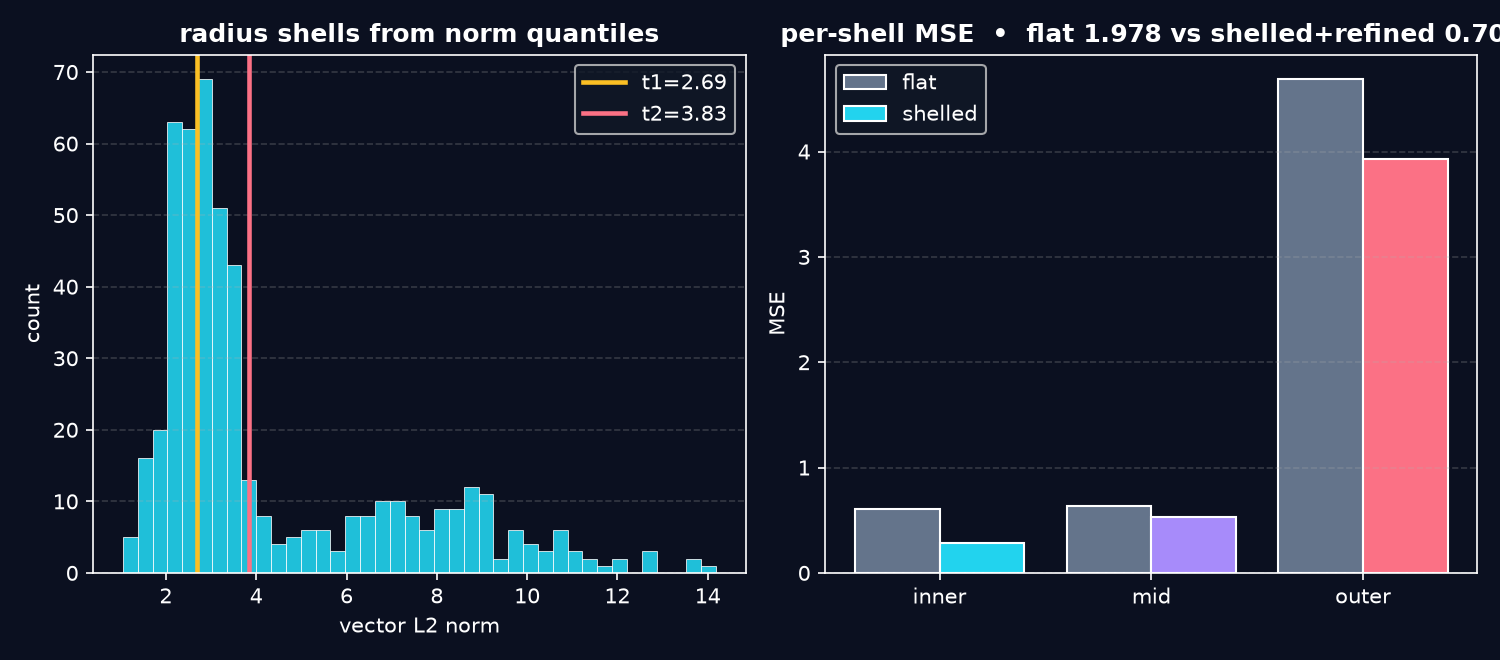
shell-vq
64.5% error cut vs flat VQ
How it works
Quantile radius shells (inner/mid/outer) + per-shell scales + gated 1-bit outer residual.
Implementation
shell_vq/core.py: build_shell_codebook, quantize_shelled, residual_refine. 6 tests.
Applications
Sub-2-bit LLM compression, vector DB weight store.
Prior art: AQLM/QTIP + Leech VQ 2603.11021 + BTC-LLM
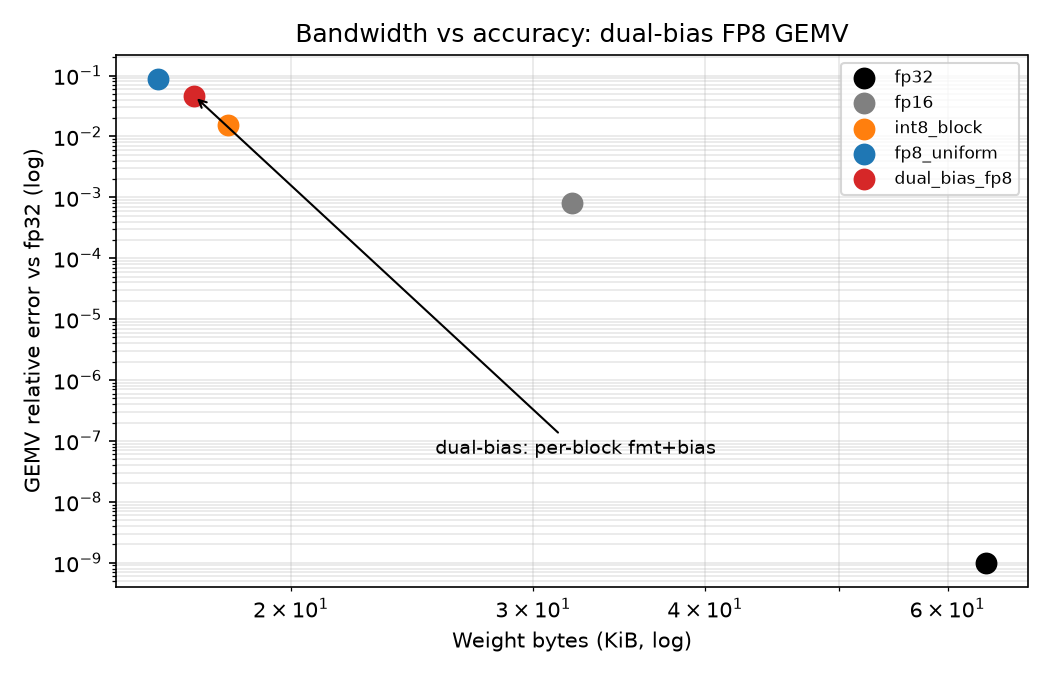
dual-bias-fp8
2x accuracy at same bandwidth
How it works
K-blocks of 32 choose E5M2 vs E4M3 by range + calibrate bias 11-19, fused dequant+GEMV.
Implementation
dual_bias_fp8/core.py: choose_format, calibrate_bias, gemv_reference. 5 pass.
Applications
GPUs without FP8 units, weight-only serving.
Prior art: FP8 spec + TensorRT/TorchAO + KV-dequant thread
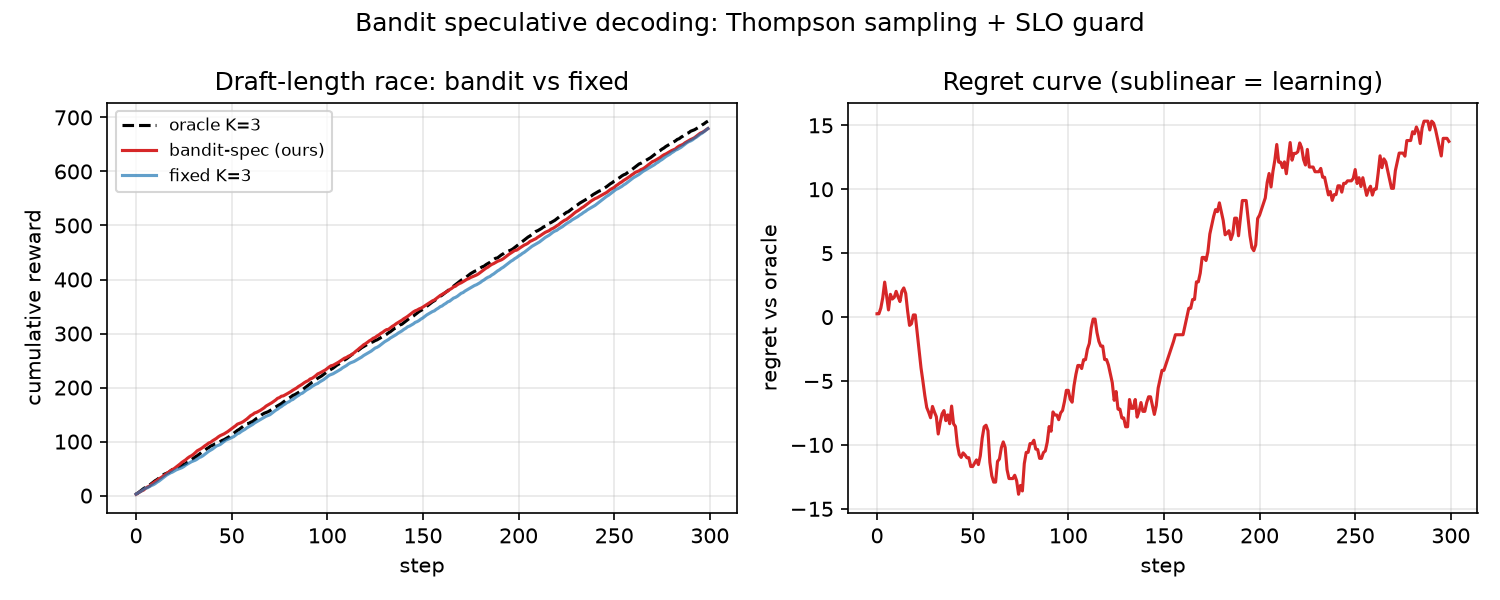
bandit-spec
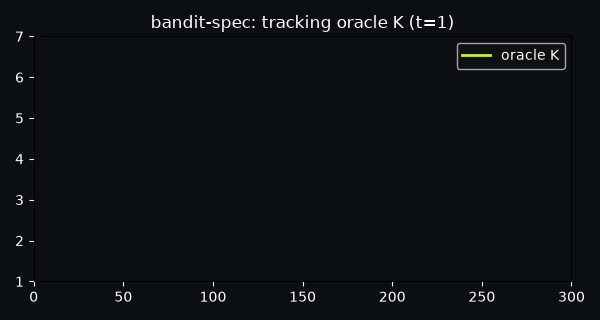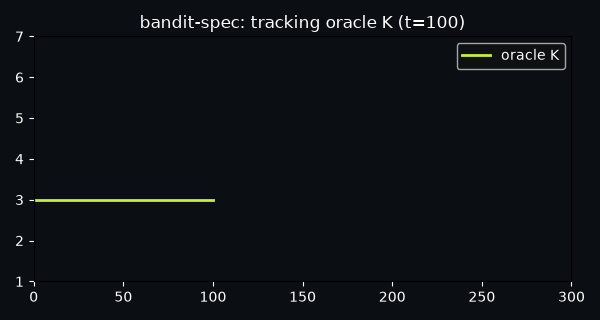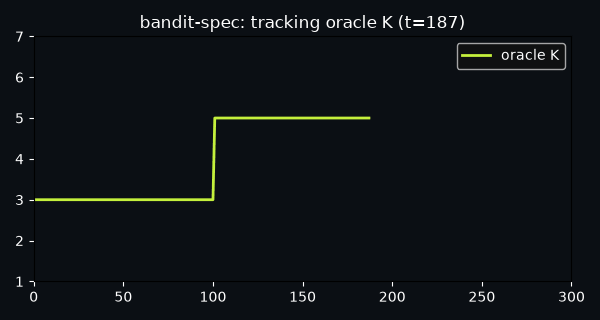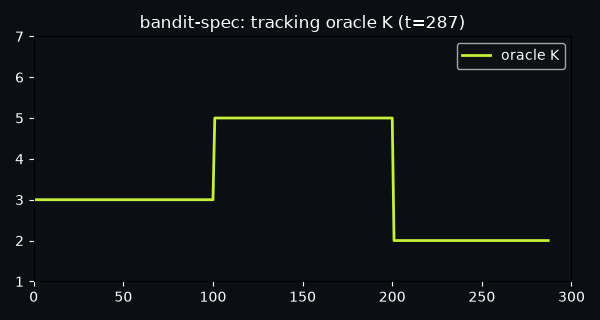
Bandit tracks oracle K=3, regret 13.7
How it works
Thompson sampling over K=1..7 with cost-normalized reward + p99 SLO veto shrink.
Implementation
bandit_spec/core.py: thompson_pick, slo_guard, BanditSpeculator. 6 tests.
Applications
Chat serving with latency SLOs, MTP draft headroom.
Prior art: Leviathan/Chen + SpecDec++ 2405.19715 + AdaSpec + Not-a-Bandit
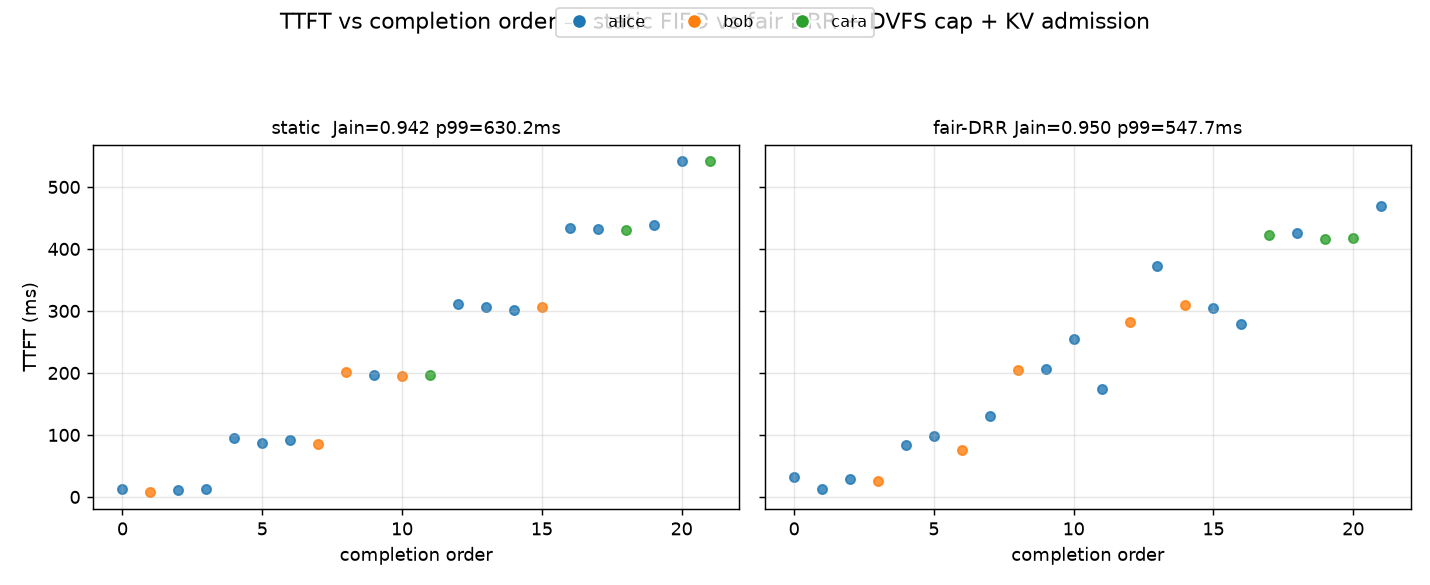
fair-batch
Jain 0.950, p99 -13%
How it works
Deficit-round-robin across users + DVFS power cap + KV-pressure admission.
Implementation
fair_batch/sim.py: jain_index, power_model, simulate_fair_continuous. 6 tests.
Applications
Multi-tenant inference, power-capped clusters.
Prior art: Orca + NanoFlow + Fair Batch 2510.14392 + KernelSight-LM
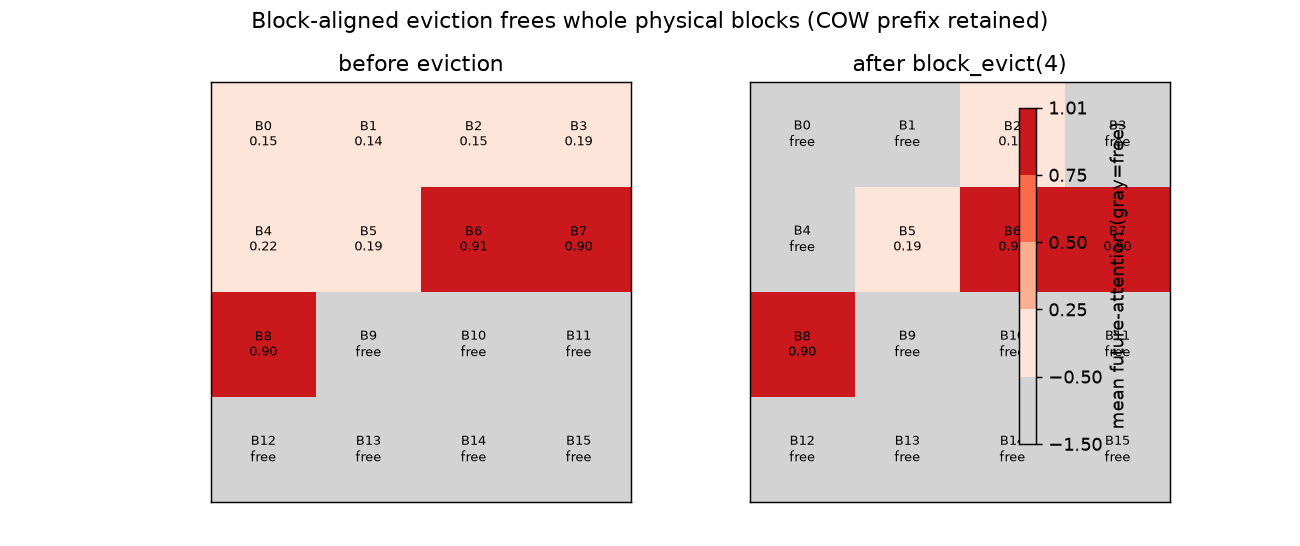
block-evict
Frees whole blocks, COW intact
How it works
Score whole blocks (mean future-attn minus frag cost), evict full prefix blocks.
Implementation
block_evict/cache.py: BlockCache + block_evict. 6 tests.
Applications
vLLM PagedAttention long-context serving.
Prior art: Kwon PagedAttention + H2O/StreamingLLM + PagedEviction 2509.04377
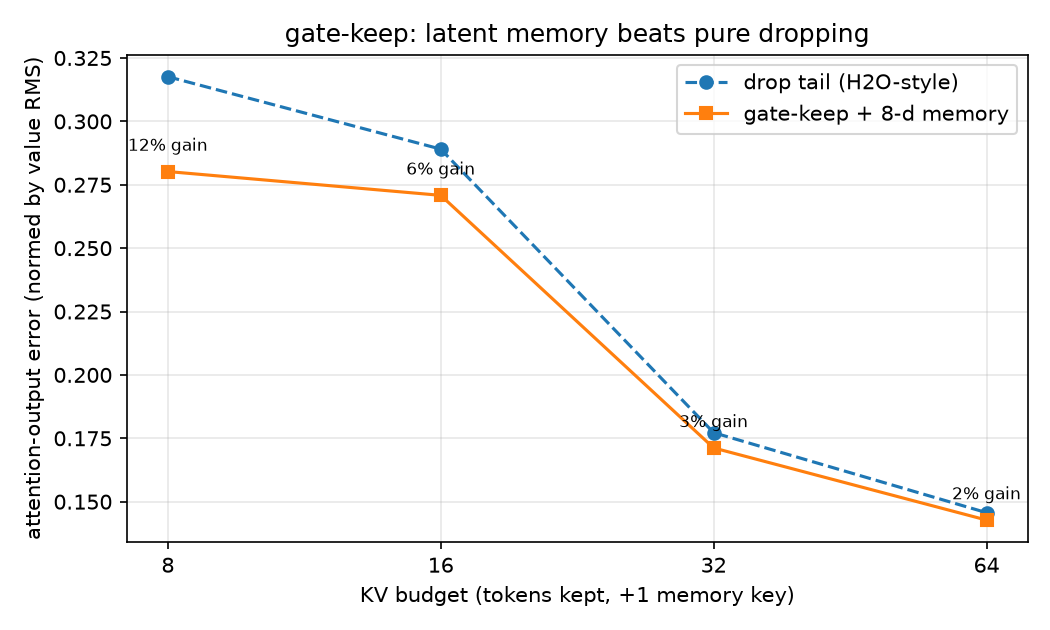
gate-keep
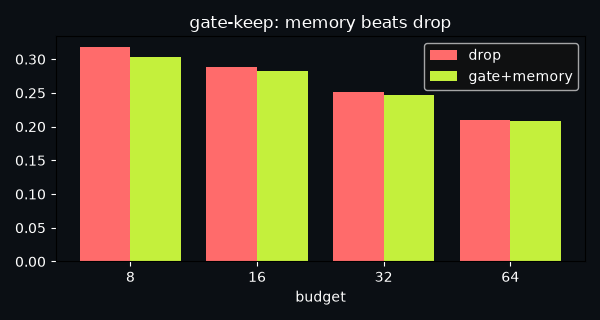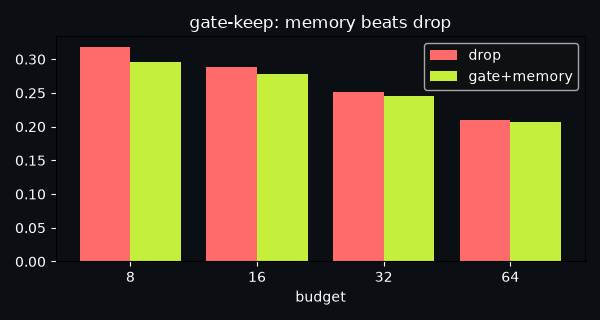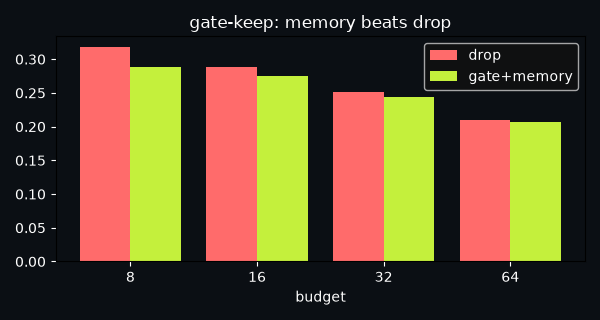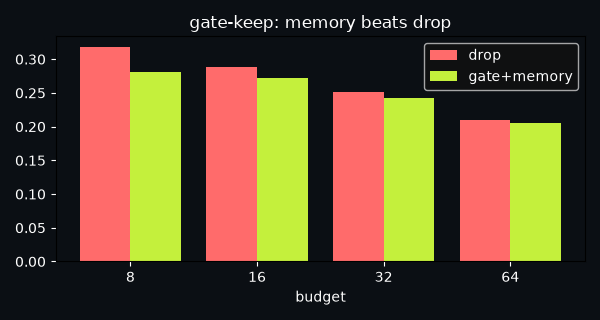
+11.8% at budget-8 vs drop
How it works
Ridge-gate predicts future importance; evicted tail compressed to 8-d latent key.
Implementation
gate_keep/compress.py: fit_gate_ridge, compress_with_memory. 5 tests.
Applications
32k+ context chat, reasoning traces.
Prior art: StreamingLLM/H2O + Gated Eviction 2601.17668
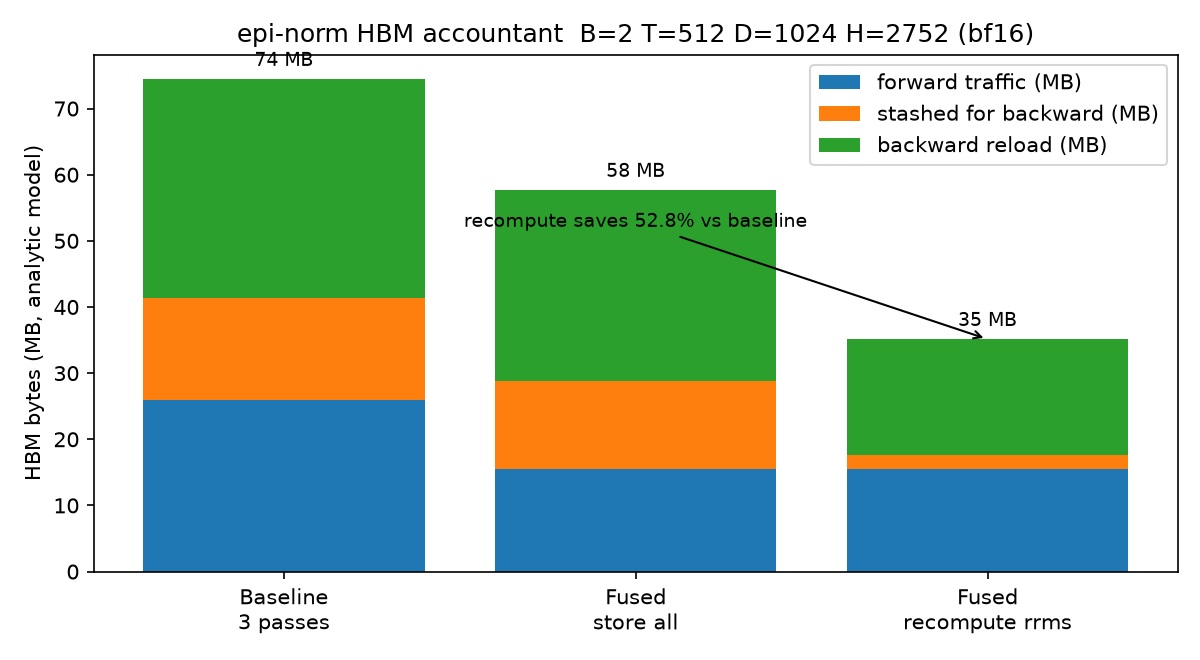
epi-norm
52.8% HBM saved (74→35 MB)
How it works
RMSNorm+residual+SwiGLU fused; recompute rrms in backward to save store.
Implementation
epi_norm/core.py: fused_epilogue_ref, hbm_accountant. 5 tests.
Applications
LLM training throughput, Liger-style kernels.
Prior art: Zhang&Sennrich + Liger + GEMM-epilogue 2605.19269
cache-roof
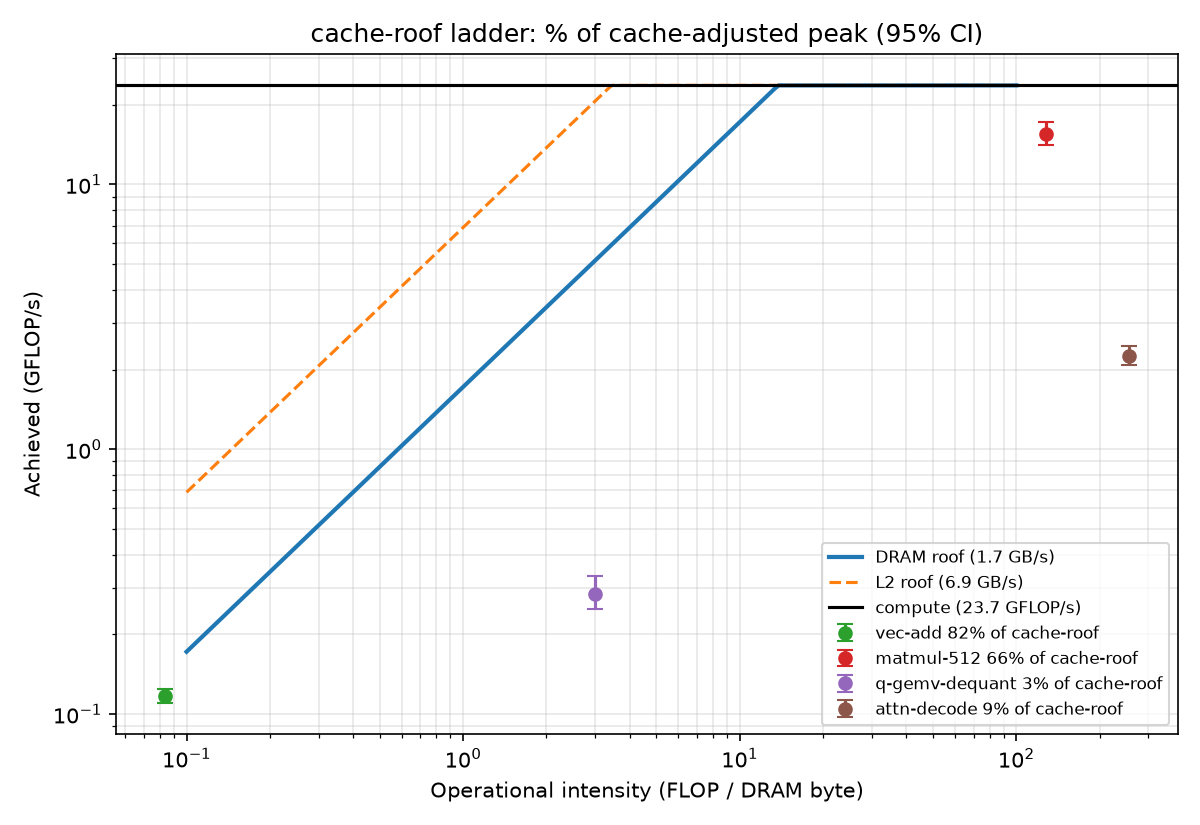
Grades 81.5% / 65.5% with CIs
How it works
L2-hit split + dequant-overlap + 95% CIs from trials, % of cache-adjusted peak.
Implementation
cache_roof/harness.py + roofline.py: time_fn, cache_adjusted_roof. 5 tests.
Applications
Kernel selection, 5090 + vLLM bench rigs.
Prior art: Williams Roofline + do_bench + KernelBench
green-roof
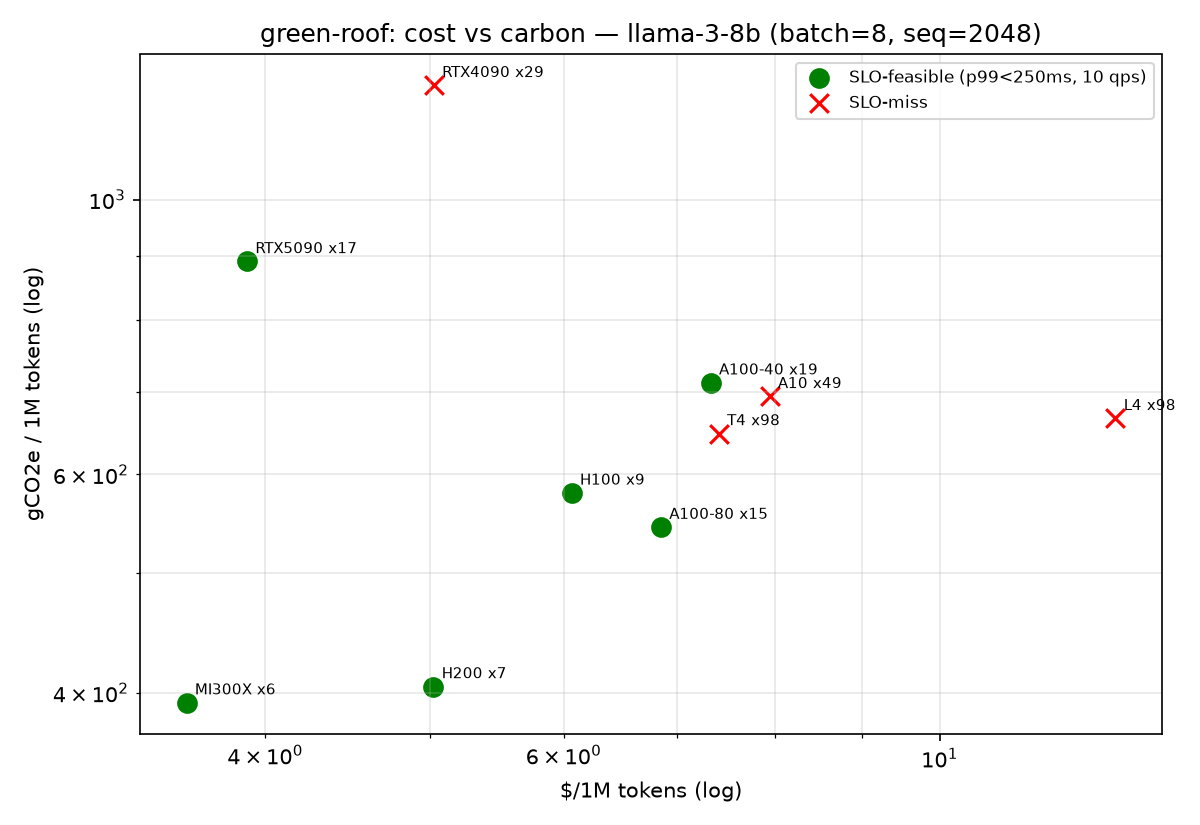
MI300X $3.59/1M, 393g CO2
How it works
Roofline + $/J/CO2 + replicas_for_slo autosolver + fair_split tenants.
Implementation
green_roof/planner.py + cli.py: plan|gpus|models|green. 8 tests.
Applications
Capacity planning, green AI quotes, SLO sizing.
Prior art: Williams + LLM Inference Unveiled + KernelSight-LM
Reproduce
python -m pytest tests -q + python demos/demo.py in each folder. Receipts in receipts/receipt.json. Deploy: push portfolio-novel/docs as GitHub Pages (Settings → Pages → Deploy from branch → /docs).